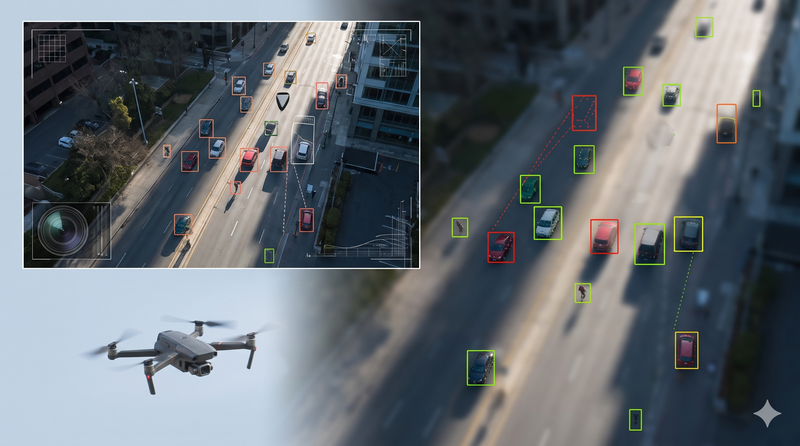
Do you remember the excitement of opening a delivery box? There is a little ritual to it: the careful slice through the tape, the rustle of packing material, and then the moment of revelation. As it turns out, some of the most amazing discoveries of our time are waiting in boxes too, even if those boxes are the dense, jargon-heavy packaging we call academic papers. Inside are breakthroughs that could change the way we live, work, and see the world. At Unboxing Lab, we want to skip the complicated equations and theoretical frameworks and get straight to the ideas that matter. Today’s box contains a study from Duksung Women’s University, led by Professor Yoo Je-hyeok, about a clever new technique called SATTA. It is an artificial intelligence calibration method designed to reduce errors when AI tries to detect tiny objects like people and vehicles in footage captured by drones. The name may sound technical, but the idea is surprisingly simple and elegant: instead of retraining an AI model from scratch, which is expensive and time-consuming, SATTA helps existing models make fewer mistakes by refining the results they already produce. In a world where drones are becoming more common in our skies, this kind of refinement could make a real difference in how we monitor traffic, respond to disasters, and keep cities safe.
To understand why SATTA is so valuable, we need to appreciate the problem it solves. Imagine a drone hovering high above a busy urban road. From that altitude, the people below are not much bigger than a few specks of dust in the footage. Cars look like tiny toys. To an AI system, identifying these small objects is incredibly difficult, because a small cluster of pixels can easily be mistaken for a person, a shadow, or a crack in the pavement. One common strategy is to slice the full image into many small segments and analyze each segment individually. This technique, known as SAHI, is like putting the image under a magnifying glass. It allows the AI to see small objects in greater detail, and it has certainly helped improve detection rates. But there is a catch. When you zoom in on tiny pieces of a larger image, the AI loses context. It starts seeing things that are not really there. A patch of shadow might become a pedestrian. A road marking might become a car. The very act of focusing on smaller areas increases the chance of false detections, because every dark smudge begins to look suspicious. It is a bit like trying to find a friend in a crowded stadium through a pair of binoculars: the binoculars help you see farther, but they also make it harder to tell whether the blurry figure in the corner is actually your friend or just someone wearing a similar jacket. The AI ends up inventing objects that do not exist, and that is a serious problem for any application that relies on accurate information from the sky.
This is where SATTA steps in. Instead of trying to improve the AI model itself, the research team decided to build a smart calibration system that works after the AI has already made its predictions. The AI detects a set of objects and assigns a confidence score to each one. SATTA takes those raw results and re-scores them, considering important clues like where an object was detected, how big it is, and, crucially, how close it is to the edge of one of the sliced image segments. The underlying logic is quite intuitive. If a detected object appears right at the boundary of an image segment, it is probably not a real, complete object. It might be just half of a car or half of a person that got sliced in two when the image was divided. These borderline detections are often incorrect, so SATTA assigns them lower scores and filters them out. It also looks at other contextual patterns and uses them to correct mistakes that the AI made. The beauty of this approach is that it does not require any retraining of the existing AI model. You do not need to feed the model a mountain of new data or spend weeks adjusting its internal weights. You simply attach SATTA to the output side of the model and let it clean up the mess. It is a little like having an experienced editor go through a rough translation written by someone who knows the language but is a bit careless. The editor does not rewrite the original text from scratch; instead, they re-read it, catch the mistakes, and adjust the phrasing. The result is a cleaner, more reliable product with relatively little extra effort. This makes SATTA a practical solution for real-world situations where retraining massive AI models is simply not feasible.
Of course, the real proof of any technique is in the numbers, and the research team put SATTA through a rigorous evaluation. They used a dataset called VisDrone2019-DET, which contains 1,610 test images taken from drone footage. They tested seven different AI configurations in total, including three models from the well-known YOLO family and four others: RT-DETR-L, DINO-R50, Cascade R-CNN, and Faster R-CNN. The results were encouraging. For the representative model YOLO11n-960, the number of false detections per image dropped by 37.5%, from 140.8 with the existing SAHI method to just 88 with SATTA. Across all the test images, false detections fell by a remarkable 84,878 cases, from 226,601 all the way down to 141,723. Particularly striking was the drop in cases where the AI mistakenly identified the background as an object: that number plunged from 131,801 to 75,179. The precision of tiny-object detection also improved, rising from 0.055 to 0.082, while a metric called XS AP50, which measures the accuracy of detecting extremely small objects, climbed from 0.105 to 0.119. Depending on the specific model and configuration, the reduction in false detections ranged from 35.5% to 39.1%, which is a substantial improvement. In other words, SATTA truly helped the AI become more careful about what it claimed to see, weeding out many of the phantom pedestrians and ghost vehicles that had been popping up in the analyzes.
But there is no such thing as a free lunch, and this study is no exception. The same filtering action that cleared away so many false detections also had a side effect: it caused the AI to miss more real objects. The number of genuine objects that the system failed to detect increased by 1,793 cases, rising from 21,782 to 23,575. The metric known as recall, which measures the proportion of real objects that the AI successfully finds, dipped from 0.480 to 0.459. This is an important trade-off to understand. Think of the calibration process like turning down the volume on a noisy radio. It is pleasing to finally silence all the static, but if you lower the volume too much, you might also lose the quiet parts of the broadcast you actually wanted to hear. In this case, SATTA’s filtering reduces the background noise of false alarms, but it also risks missing some faint, legitimate signals. This means the technique is particularly useful in situations where false detections are more harmful than missed detections. For example, if you are using drones to measure road traffic, you might prefer to have a system that rarely reports a car that is not there, because false reports could lead to inaccurate data and wasted resources. On the other hand, if you are searching for a missing person in the aftermath of a disaster, missing a real human life because the algorithm was too cautious could be devastating. The researchers are honest about this limitation. They are not presenting SATTA as a magic cure that solves every problem; they are offering it as a calibrated tool that can be adjusted depending on the needs of the task.
Behind this technical achievement are real people, and their story makes the discovery even more inspiring. The study’s first author is Seo Hae-in, a student at Duksung Women’s University’s Department of Data Science, with Kang Ye-eun contributing as co-author. This is not a story about a giant corporate lab with endless resources; it is a reminder that fresh ideas and serious scholarship can come from undergraduates working alongside their professor. Their paper was accepted for the evaluation and datasets track at WACV 2027, the Winter Conference on Applications of Computer Vision, an international gathering of researchers from around the world. That is a meaningful recognition, because it means their work stood up to the scrutiny of an international academic community. The possible applications for SATTA are broad and exciting. Drones are becoming more common in fields like traffic monitoring, where accurate counts of vehicles and pedestrians are essential for planning safer roads. They are also used to inspect urban environments for potential hazards, such as structural damage or dangerous crowds. And in the chaos after natural disasters, drones can become lifelines, searching through wreckage for people who need help. A tool like SATTA can make all these applications more trustworthy by reducing the number of phantom objects that distract and mislead. It will not replace retraining models, but it offers a new, faster path to better performance. The unboxing of today’s study leaves us with a sense of wonder: the next time we see a drone humming overhead, we might think about the invisible machinery of ideas, calibrations, and careful tweaks that are helping it make sense of the world below. And that is a discovery worth unwrapping.