To understand how well an automatic system can spot discourse derailment—the moment when a conversation stops being a conversation and slides off the rails—the researchers built two reference points. The first was a deliberately simple baseline based on sentiment analysis, a tool that measures how positive, negative, or emotionally charged a piece of writing is. Sentiment analysis is a natural starting point because it has been used to detect fake news and other forms of problematic online content. The idea was to see whether emotional tone alone could predict whether a reply derails a discussion. It could not, at least not in a straightforward way. Across the real replies that human raters had scored, sentiment correlated only weakly with derailment ratings: the correlation with overall sentiment was -0.06, with negativity -0.13, and with positivity -0.17. All of these were negative and statistically significant, meaning that as derailment increased, messages actually became less emotional, not more. This is a striking finding because many people assume that derailing or toxic comments are full of strong feelings. Instead, the most derailed messages seemed to lack meaningful engagement altogether. They were not angry rants; they were, in a sense, empty. This fits with the observation that high derailment is often associated with the absence of the strategies that normally hold a conversation together. So while sentiment analysis was too weak to be a serious detection tool, it served a useful purpose: it set a low bar and made it clear that any automatic model worth its salt would have to look beyond emotion.
At the other end of the spectrum, the researchers created a “topline” model to see how well derailment could be predicted if an algorithm had access to all the information a human annotator could provide. This model used twenty-five manually tagged discourse features and a random forest of decision trees. The most powerful predictor was endophoric reference, meaning whether a comment refers back to something already said in the discussion. If a reply did not refer back to the previous message, the conversation was far more likely to be judged as derailing. The next most important features included non-sequiturs, red herrings, expressions of sympathy, qualitative exploration of the topic, ad hominem attacks, and exploration of space. The decision tree revealed that derailment is not one single thing. Some derailing messages were completely off-topic and logically incoherent: they neither referenced prior topics nor followed logically from the previous message. Others were “strategy-absent”: they did not show obvious logical flaws, but they also made no attempt to connect, sympathize, explore, or engage. A third group used ad hominem attacks while still exploring the topic qualitatively, but crucially lacked both direct references to the preceding discussion and any expression of sympathy. Finally, some messages stayed on topic but built flawed logical connections or dragged the conversation toward a side issue. The random forest model that combined all of these patterns explained about 55% of the variance in human derailment ratings, and its predictions correlated strongly with human judgments, with a Spearman correlation of 0.78. The analysis showed that logical fallacies, the absence of sympathy, and the presence or absence of topic reference are the core signals of derailment—and these are exactly the signals that are hardest to capture automatically using simple word lists or surface cues.
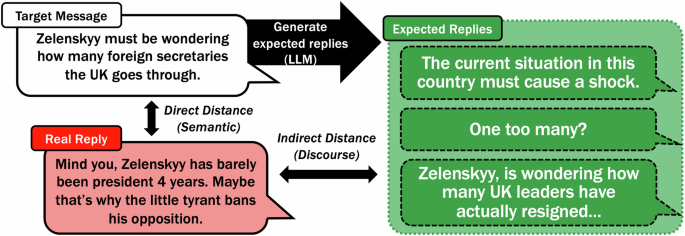
The automatic system itself was built around semantic distance measures rather than hand-coded discourse features. In the indirect approach, the programme took a real reply and compared it with a deliberately “derailed” version generated by a language model, producing a score called realToGenerated. Higher scores meant the real reply was closer to the derailed version, and therefore more likely to be derailing itself. This score was positively correlated with human derailment ratings, with a Spearman correlation of 0.371. A mixed-effects regression confirmed that the automatic estimate was a strong predictor of human judgments, with a coefficient of 5.50 and confidence intervals far above zero. Leave-one-out cross-validation strongly favoured the model that included the automatic measure, giving it about one hundred times more weight than a model without it. When the predictions were turned into a simple binary decision—derailing or not—the system achieved an accuracy of 70.7%, with precision around 0.39, recall around 0.63, and an F1 score of about 0.485. These numbers were significantly better than chance, and the result held even after controlling for video-level effects, message type, and reply length. The authors also tested a direct measure called targetToReal, which compared the real reply with an ideal, on-topic target message. This measure added something unique, and combining the two semantic distances improved accuracy slightly to about 71.5%. The final programme therefore used both measures in a simple linear regression, with the decision rule: a message is derailing if 3.41 minus 2.244 times the indirect score minus 0.825 times the direct score exceeds 2.95. Interestingly, the automatic model worked well for top-level comments and replies, but not for pairs that started from a video title. The authors suspect this is because video titles are broad, journalistic, and selective in a way that human viewers implicitly understand, while the language model treats them as concrete and specific. This mismatch made the automatic predictions unreliable for that small subset of message pairs.
To test whether the model could generalise to videos it had never seen, the researchers ran a 10-fold cross-validation. They trained the model on messages from 90% of the videos and tested it on messages from the remaining 10%, repeating the process ten times. The results were almost identical to the earlier statistical analysis: average precision was about 0.399, recall about 0.607, F1 around 0.479, and accuracy around 71.6%. This consistency was encouraging because it meant the model was not overfitting to one particular set of videos; it was genuinely learning something about how derailment works in this type of online discussion. The team then explored a more global measure. Instead of comparing each reply only to the message immediately before it, they compared it to the top-level comment that started the thread. The intuition was that a conversation can be locally coherent but globally derailing: a reply might follow the previous comment smoothly while the thread as a whole has drifted far from its original subject. This global measure, called topToReal, was actually more strongly correlated with human derailment ratings (Spearman’s rho = 0.489) than the local indirect measure. Adding it to the model improved performance considerably, raising accuracy to 77.5% and F1 to 0.54, mainly because it reduced false positives. The improvement makes sense if human raters are taking the broader thread context into account when they judge whether a message has derailed. The global measure may also be capturing how general or specific the original topic was: if a top-level comment is very broad, it is harder to go off-topic because nearly anything can be seen as relevant. One extra curiosity was that the number of likes a reply received had no significant correlation with human derailment ratings. Social approval, at least in this dataset, was not a useful signal for spotting derailment.
When all the models were compared side by side, the picture was clear. The sentiment baselines performed the worst, as expected. The topline model, which had access to all twenty-five human-coded discourse features, performed the best. The automatic system sat in between: roughly twice as effective as the baselines, but only about half as good as the topline. This is a respectable result for a zero-shot system, meaning it was not trained or fine-tuned for this specific task. Perhaps the most interesting comparison was with human agreement. The automatic models performed about as well as two independent human annotators agreed with each other. In other words, the gap between the automatic system and a typical human rater is not enormous. The authors point out that this suggests there may be a practical ceiling on how much better any model can get until the concept of discourse derailment itself is refined and defined more precisely. It might seem strange that the topline model could outperform a human rater, but there is a simple explanation: the topline model used discourse features coded by the same person who made the derailment judgments. That gave it access to internally consistent information that an independent human coder would not have. The automatic system, by contrast, had to infer everything from raw text, and it still managed to land in the same ballpark as human judgment. That is a meaningful achievement, though it also highlights how much room there is for improvement.
The final question was what the automatic model was actually paying attention to. Since large language models are difficult to inspect directly, the researchers used the same random forest technique, this time trying to predict the automatic scores from the human-tagged discourse features. The conditional inference tree for the automatic ratings was simpler than the tree for human ratings, and it placed much more weight on exploration of the topic—qualitative, spatial, and temporal exploration—rather than on logical and attitudinal strategies. Both humans and the automatic model relied heavily on endophoric reference, but the automatic model gave less weight to non-sequiturs, ad hominem attacks, and expressions of sympathy. This pattern makes sense if the automatic system is using lexical and semantic proxies for discourse features. Coherence signals such as deictic words, place names, temporal expressions, and other surface markers are relatively easy to detect from wording alone. Logical fallacies and the emotional quality of empathy are much harder to recognise without deeper understanding. In other words, the automatic system seems to be biased toward the surface-level, coherence-related aspects of derailment and underuses the logical and attitudinal dimensions that humans find important. The authors conclude that discourse derailment is a complex, multidimensional phenomenon. Reducing it to any single cue—whether negative sentiment, a red herring, or even a non-sequitur—gives an incomplete picture. The automatic model is promising because it already captures a substantial portion of what humans mean by derailment, but to improve it further we will need a clearer definition of the concept, better ways to handle context and world knowledge, and more sophisticated methods for detecting the logical and emotional moves that keep a conversation on track.