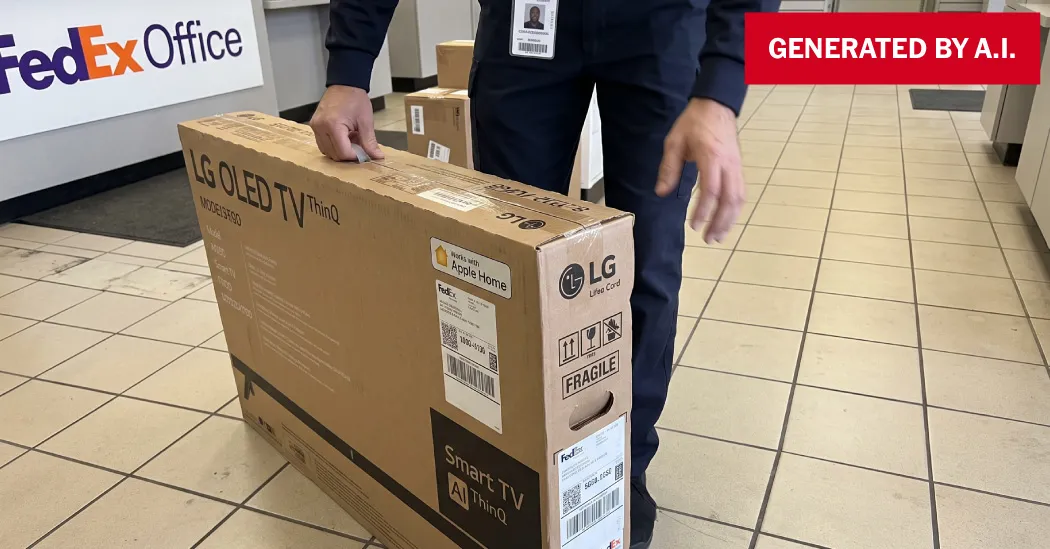
At first glance, it looks like an ordinary snapshot taken inside a FedEx Office store. An employee in a vest holds a package; shelves and signs fill the background; fluorescent lighting gives everything that familiar retail glow. The image is crisp, well-composed, and completely believable. But it isn’t real. It was generated by Google’s Gemini, an AI chatbot, from a simple text prompt. The fact that this image can pass for a photograph tells us something important about how far AI image generation has come—and how much harder it is becoming to trust our own eyes. A few years ago, AI-generated pictures were full of absurd mistakes: melting faces, extra fingers, gibberish text, impossible anatomy. People could spot them almost instantly. Those days are gone. The fingers in this image are pixel-perfect, complete with natural creases and veins. The text on signs and packages is legible, down to the correct fonts and logos. The lighting is consistent, the perspective is almost convincing, and the overall composition has the casual, unposed feel of a real workplace photograph. The technology has improved so rapidly that the old tells have all but disappeared. Yet even in this nearly flawless image, trained experts can find subtle clues that reveal its artificial origin. The challenge now is not seeing obvious errors, but learning to recognize the quieter, deeper ways AI gets the world wrong. This single image is a kind of test—a way to see if you can still tell the difference between a photograph and a simulation. And it is a reminder that visual skepticism is no longer optional; it’s becoming a survival skill for the digital age.
One of the most revealing clues lies in something we rarely notice consciously: perspective. Human artists and photographers naturally understand that parallel lines converge as they recede into the distance, creating a consistent grid that anchors a scene. AI generators, for all their sophistication, still struggle with that geometry. Look closely at the tile floor in the FedEx Office image. The grout lines between the tiles should form a neat, orderly grid that leads the eye toward the back of the store. Instead, when researchers traced them, the lines wandered in different directions, curving and bending as if the floor were warped. It’s the kind of mistake that is easy to miss at a glance but becomes obvious once you look for it. Another clue has to do with the way AI responds to prompts. When a user asks for a scene, they’ll often include specific keywords—here, something like “FedEx Office.” The system, eager to satisfy the request, tends to overreact to those words. It places the signage and branding front and center, even when that doesn’t quite make sense for the scene. A real photograph of an employee holding a package might not have the store’s logo so prominently and repeatedly displayed; it would appear naturally in the environment, not as a set of visual emphasis markers. This overemphasis is a subtle but reliable sign that an image was generated by a model that latched onto the words in the prompt rather than understanding how a real physical space is organized.
Another place where AI still trips up is text—especially when you zoom in. The big, bold signs in the image look convincing at first, but smaller letters often break down into nonsense. The AI has learned to generate shapes that look like writing, but it doesn’t truly understand language. So while a headline or logo might appear clean and correct, smaller text can become garbled, with strange letterforms or soft, shadowy smudges over individual characters. That slight blur or drop-shadow effect is often a giveaway of machine-generated imagery, because the model is trying to smooth over something it doesn’t really know how to render. The same underlying confusion shows up in objects that have rules. Consider the ID badge hanging from the employee’s lanyard. The badge itself looks fine: it has a portrait, a logo, and some text. But if you look closely at how the lanyard attaches to the badge, you’ll notice it doesn’t actually connect. The strap just sort of floats behind the plastic cover, not attached to any visible clip or hole. AI systems can get the overall appearance of an object right, but they don’t understand the physical relationships between parts. They know what a badge looks like, and they know what a lanyard looks like, but they don’t know that the lanyard has to thread through a clip to hold the badge. The same kind of mistake appears in the man depicted on the badge: his skin tone doesn’t match the employee holding the box. The AI got the individual elements visually correct but failed to make them coherent as a scene.
Perhaps the most telling clue is how AI handles meaning. It can generate text that looks like English, but it doesn’t understand what the words mean. Take the television box in the background. The slogan on it looks like it’s trying to say “Life’s Good,” the well-known LG motto. But when you zoom in, the letters actually spell “Lifea Cord.” It’s close enough to pass a quick glance yet completely nonsensical. The model has learned the visual pattern of letters and words, but not their semantics. The same issue appears with the symbols on the side of the package. The first two icons are mostly accurate: one means “this side up,” and the other means “fragile.” But the third square contains a symbol that doesn’t exist in any standard packaging guide. It looks plausible—maybe a warning about something—but it’s a made-up graphic. The AI knows that packages often have warning symbols, so it generated a generic one without understanding what those symbols are supposed to mean or which ones are actually used. There’s also the odd image on the television box itself. It shows the base of a TV set, but the rest of the television is missing. Where is the screen? Where is the stand going? The image is fragmented in a way that a human photographer would never accidentally capture, because humans understand that a product box should show the whole product, or at least a recognizable part of it. These mistakes are subtle, but they all point to a deeper truth: AI generates images by pattern-matching vast amounts of data, not by understanding the physical and logical rules of the world. It can put together the pieces of a scene with astonishing accuracy, but it doesn’t really know what those pieces mean.
This innocuous-looking image represents the next frontier in AI-generated imagery. In some ways, it’s more impressive than the hyper-stylized, obviously fake pictures that went viral in earlier years. It demonstrates that AI can now produce realistic, mundane, everyday scenes—the kind of photograph you might scroll past without a second thought. That is precisely what makes it so dangerous. When AI could only create surreal landscapes or people with six fingers, it was easy to dismiss it as a novelty. But now that it can generate a believable image of an employee in a store, the line between documentation and fabrication starts to blur. We can no longer assume that a photograph is real just because it looks real. Experts are beginning to train themselves to look for these subtle flaws: warped perspective, meaningless text, disconnected objects, impossible symbols, and other artifacts that reveal the machine’s hand. These are not permanent weaknesses. AI models are improving every day, and the mistakes that exist today may be corrected tomorrow. The arms race between image generation and image detection is ongoing, and it is moving swiftly. What remains constant is the need for critical thinking. Instead of asking “does this image look real?” we may need to ask “is this image plausible in the real world?” and “who created it, and why?” Those questions are harder to answer with a glance, but they are becoming essential.
In the end, the FedEx Office image is a lesson about human perception as much as about artificial intelligence. We like to believe that seeing is believing, that our eyes are reliable witnesses to the world. But photographs have never been pure, unmediated truth. They are framed, edited, staged, and sometimes manipulated. AI simply takes that manipulation to a new level, one where the tools are available to anyone and the results are often indistinguishable from reality. The good news is that our brains are remarkably good at noticing inconsistencies once we know they might be there. With a little training, you can learn to spot the subtle signs of AI fakery—at least for now. But the deeper lesson is not just about learning to spot fake images. It’s about becoming more thoughtful about all visual information we encounter online. We should ask where an image came from, who shared it, and why it exists. We should look at the details, but also at the context. We should be humble about our own ability to tell real from fake, and generous in our willingness to verify before believing. The image of the employee holding a package is not just a picture; it’s a reminder that the future of knowing is not about seeing clearly, but about thinking carefully. And that challenge is one we all share.